Project information
- Name: Forest Fire Prediction
- Type: Personal
- Project date: 22 Dec,2022
- Project URL: Deployed App Link

Forest Fire Prediction
Machine Learning Project
Explore my Repositories. »
Introduction
·
Data Information
·
Contact
About The Project
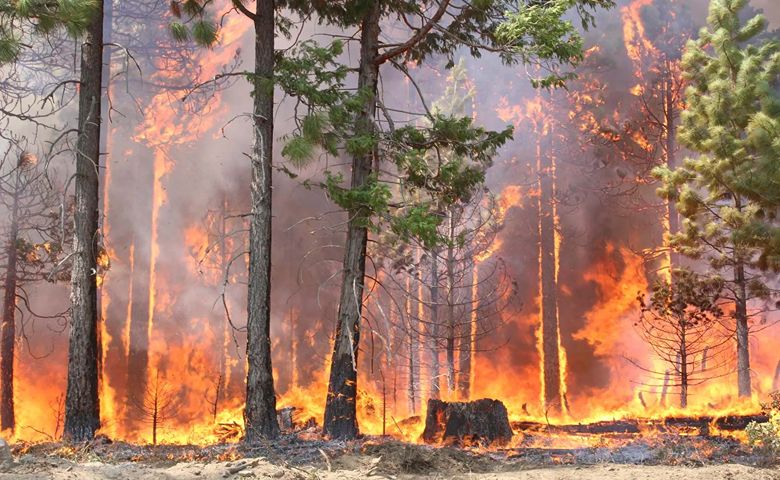
- This project aims to predict forest fire using best machine learning models. Regression and Classification both streams Supervised learning is portrayed in this project. The dataset used in this project is taken from UCI Machine Learning Repository - Algerian Forest Fire Dataset. Both Single input and Bulk input prediction can be exceuted.
Deployed app

Introduction
- In this project, i have worked on solving Regression and Classification both with a usecase of predicting the Forest Fire Weather index and Forest Fire possibility.The dataset used in this project is taken from UCI Machine Learning Repository - Algerian Forest Fire Dataset. MongoDB database is used to store the dataset. EDA and Model Building both could be found in the repo. Logging is maintained accordingly.
Dataset Information
-
Download the original dataset here : Algerian Forest Fire Dataset
-
The dataset includes 244 instances that regroup a data of two regions of Algeria,namely the Bejaia region located in the northeast of Algeria and the Sidi Bel-abbes region located in the northwest of Algeria.
-
The period of data is from June 2012 to September 2012.
-
The dataset includes 11 attribues and 1 output attribue (class)
-
The 244 instances have been classified into 'fire' (138 classes) and 'not fire' (106 classes) classes.
-
Attribute Information
Date: (DD/MM/YYYY) Day, month ('june' to 'september'), year (2012) Weather data observationsTemp: temperature noon (temperature max) in Celsius degrees: 22 to 42RH: Relative Humidity in %: 21 to 90Ws:Wind speed in km/h: 6 to 29Rain: total day in mm: 0 to 16.8 FWI ComponentsFine: Fuel Moisture Code (FFMC) index from the FWI system: 28.6 to 92.5Duff Moisture Code (DMC): index from the FWI system: 1.1 to 65.9Drought Code (DC): index from the FWI system: 7 to 220.4Initial Spread Index (ISI): index from the FWI system: 0 to 18.5Buildup Index (BUI): index from the FWI system: 1.1 to 68Fire Weather Index (FWI): Index: 0 to 31.1Classes: two classes, namely 'fire' and “not 'not fire'
Steps
- Installing Python, PyCharm, Monogodb, Git to Computer.
- Creating Flask app by importing
Flaskmodule. - Download the source dataset from UCI Repository.
- For Classification algorithm decided to predict the features
Classesfrom the dataset which is Binary classification(fire, not fire). - For Regression Problem algorithm decided to predict the feature
FWI(Fire weather Index) which is 90%+ correlated to Classes Feature.
Loading CSV and Inserting to DB
- The Downloaded CSV file is loaded as pandas Dataframe using Pandas Library.
- Pandas Dataframe is converted to Dict .
- Mongodb Altas is used as DB here, with
pymongo librarymongodb is connected to python. - Database and collections created via python and the list of dictionaries is uploaded using
collection.insert_manymethod.
EDA
- In this step, we will apply Exploratory Data Analysis (EDA) to extract insights from the data set to know which features have contributed more in predicting Forest fire by performing Data Analysis using Pandas and Data visualization using Matplotlib & Seaborn.
- It is always a good practice to understand the data first and try to gather as many insights from it.
Model Building
- For Regression Problem algorithm decided to predict the feature
FWI(Fire weather Index) which is 90%+ correlated to Classes Feature. - Models used : Linear regression, Lasso Regression, Ridge Regression, Random forest, Decision tree, K-Nearest Neighbour regressor, Support Vector Regressor.
- For Classification algorithm decided to predict the features
Classesfrom the dataset which is Binary classification(fire, not fire). - Models used : Logistic Regression, Decision Tree, Random Forest, XGboost, K-Nearest Neighbour.
Model Selection
- HyperParameter Tuning Randomized Gridsearch CV is done for top 2 models for both Regression and Classification.
- For Classification
Stratified Kfold Cross-Validation metricsis used based best Mean CV Accuracy Model is used for Model Deployment. - For Regression
R2 score metricsis used to select best model The R2 score is one of the performance evaluation measures for regression-based machine learning models.
Flask
- Importing the Flask module and creating a Flask web server from the Flask module.
- Create an object app in flask class with
__name__which represents current app.py file. - Create
/route to render default page html. /predict_apiroute for api testing usingPostman- Create a route
/predict/predictRto get user input for Classification and Regression respectively. - Run the flask app with
app.run()code.
Heroku Deployment
- Create new repo in Github and push all the data using
Git. - Install Heroku CLI and login using
heroku loginand setup the app in Heroku Web. - Connect with app
heroku git:remote -a appname - Push to Heroku using
git push heroku main
Requirements
- Python 3.7
- Numpy
- Pandas
- Flask
- Checkout requirements.txt for more information.
Technologies used



Tools used


Contact